Intelligent Flask Applications
A curated collection of production-grade Flask architectures, AI agent workflows, real-time computer vision hubs, and asynchronous worker topologies.
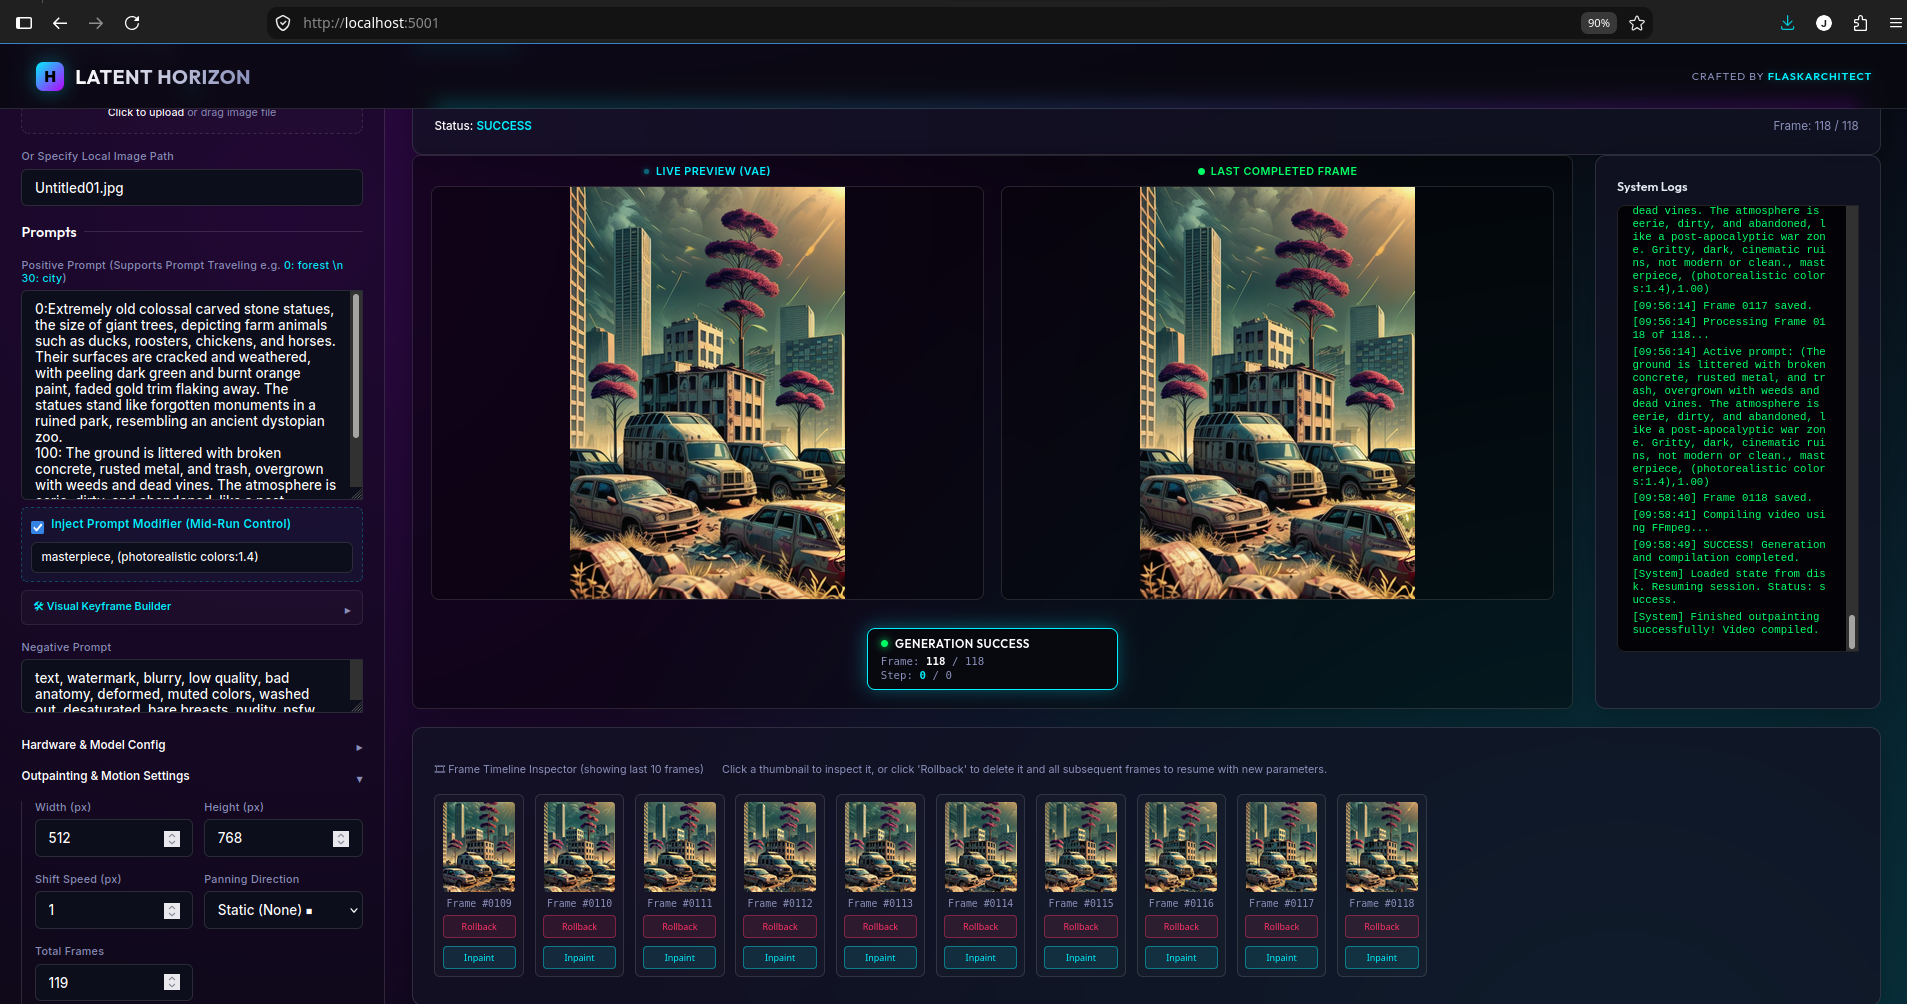
Latent-Horizon AI SLERP Video Creater
Blending & Interpolation in Stable Diffusion
Latent Space Prompt Blending & Interpolation in Stable Diffusion 🌀
In recursive image-to-image feedback loops (like Latent Infinite Zoom), transitioning smoothly between completely different visual concepts is a major challenge. If you simply change the prompt text abruptly between frames, the generation engine will undergo a jarring visual "cut," destroying the continuity of the zoom.
Instead of blending prompts as text strings, the engine in [LatentHorizon.py]
Latent-Horizon/LatentHorizon.py) performs Latent Space Prompt Blending—interpolating the raw numerical embedding vectors produced by the CLIP text encoder.
---
1. Theoretical Background: From Text to Latent Vectors
To understand latent space blending, we must look at how Stable Diffusion processes written language.
The Tokenizer and Text Encoder
1. Tokenization: Stable Diffusion cannot read letters. When you pass a prompt, a tokenizer breaks the text into word fragments ("tokens") and maps them to unique integers from its vocabulary. 2. Padding/Truncation: The pipeline standardizes prompt lengths to exactly 77 tokens (for Stable Diffusion 1.5). If a prompt is shorter, it is padded with empty/special tokens; if it is longer, it is truncated. 3. The CLIP Text Encoder: These 77 tokens are passed through a neural network (CLIP) that projects each token into a 768-dimensional space. The result is a prompt embedding tensor of shape(1, 77, 768).
These embeddings represent the semantic concept of your prompt. Words like "ocean" and "water" will lie close to each other in this 768-dimensional coordinate system, while "fire" will lie far away.
---
2. Why Text Concatenation Fails
If you want an image that is $40\%$ "abandoned office" and $60\%$ "maintenance shop," a naive approach would be to concatenate the text strings:
"An abandoned office with trash and debris, a maintenance shop room filled with tools and cleaning supplies"This fails for several critical reasons:
- Token Position Bias: Stable Diffusion pays more attention to the beginning of the prompt. The "office" elements will dominate because they appear first.
- Cross-Attention Clutter: The UNet's cross-attention layers attempt to resolve all noun-adjective pairings simultaneously. This causes visual artifacts, weird hybrid objects (e.g., an office chair made of brooms), and chaotic layouts.
- Lack of Direct Control: You cannot specify numerical fractions (like exactly $44\% / 56\%$) via raw text, as words interact non-linearly.
3. The Solution: Vector Interpolation (Embedding Blending)
Instead of mixing words, we mix the output tensors of the text encoder.
If we encode Prompt A (E_A) and Prompt B (E_B) separately, we obtain two tensors of shape (1, 77, 768) representing the raw semantic spaces of both descriptions. We can then perform a weighted mathematical average (linear combination) of these vectors before feeding them into the UNet.
The Mathematics: Linear Interpolation (LERP)
For two prompts $A$ and $B$, and a blending weight $w$ (where $0.0 \le w \le 1.0$), the blended embedding $\mathbf{E}_{\text{blended}}$ is calculated as:
$$\mathbf{E}_{\text{blended}} = w \cdot \mathbf{E}_{A} + (1 - w) \cdot \mathbf{E}_{B}$$
For multiple prompts, the calculation generalizes to:
$$\mathbf{E}_{\text{blended}} = \frac{\sum_{i} w_i \cdot \mathbf{E}_i}{\sum_{i} w_i}$$
Because the text encoder has already translated the semantic meaning of the words into numerical coordinates, linear interpolation mathematically glides the prompt coordinates through the high-dimensional latent space. The UNet receives a single, mathematically cohesive tensor that guides the generation towards a natural hybrid of both environments.
[!NOTE]
LERP vs. SLERP: While VAE latent images (representing spatial pixel layouts) are often interpolated using Slerp (Spherical Linear Interpolation) to maintain vector magnitudes on a hypersphere, standard Lerp (Linear Interpolation) works exceptionally well for CLIP text embeddings because the attention mechanism relies on dot products, where directional magnitude scaling correlates closely with guidance influence.
- Zero-copy high performance pipeline
- Role-based access control
- Integrated OpenTelemetry distributed tracing
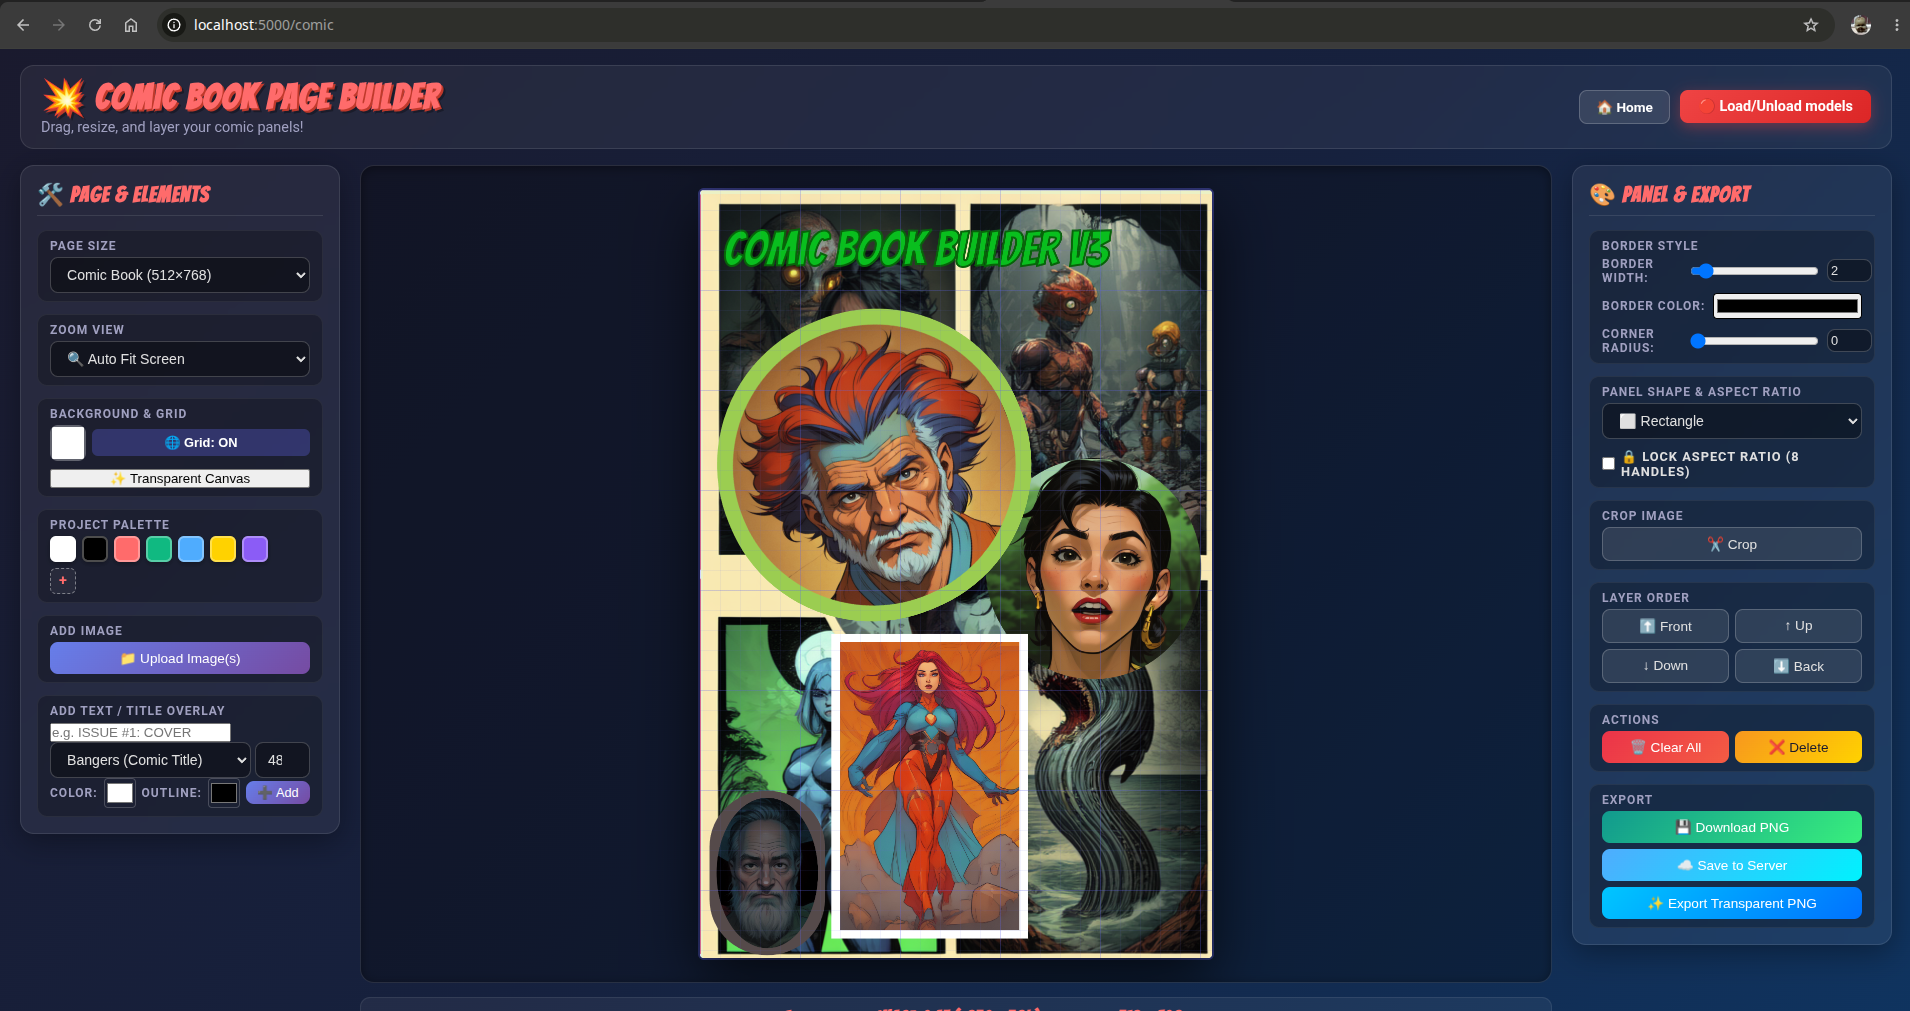
Comic Book Video Maker
ZoomPan Studio, Comic Builder & AI Generation Engine
🚀 Advanced Control & Creative Workflow Guide
ZoomPan Studio, Comic Builder & AI Generation Engine
This guide covers advanced techniques for professional AI comic production, non-destructive asset management, multi-model blending, and decoupled keyframe animation.
---
📸 1. The "Dream & Restyle" Workflow (Image-to-Image)
Decoupling your Comic Story Metadata (JSON) from your Artwork (Images) allows you to restyle or upgrade your comic pages infinitely without losing a single camera zoom point or speech bubble.
How Image-to-Image (img2img) Works
When you feed a rendered comic page or layout sketch into the AI generator with Image-to-Image mode, the Denoising Strength slider controls how much the AI modifies the original artwork:
| Denoising Strength | Mode & Purpose | What Happens | Keyframe Alignment |
| :--- | :--- | :--- | :--- |
| 0.15 – 0.35 | Enhance & Restyle | Keeps 75%–85% of exact panel lines & layout; adds rich lighting, comic shading, & textures. | 100% Perfect Alignment with JSON camera keyframes. |
| 0.40 – 0.60 | Refine & Evolve | Retains character poses & composition while updating background detail & line art. | High Alignment; minor tweaks may be needed. |
| 0.70 – 0.90 | Re-Imagine | Uses the source image only as a loose color/shape guide for a fresh interpretation. | Fresh canvas layout. |
Step-by-Step "Dreaming" Process
1. Layout & Draft: Create your comic page layout in the Comic Builder (/comic) or upload a rough sketch.
2. Keyframe Camera Motion: Open ZoomPan Studio (/), place your camera zoom points on panels, add speech bubbles, and save your project JSON.
3. Dream & Restyle:
* Open the AI Generator (/generation).
* Select 🖼️ Image-to-Image mode.
* Enter your base page filename (e.g. comic-page-abc123.png).
* Set Denoising Strength to 0.25.
Enter your art style prompt (e.g. "dark superhero comic, dramatic rim lighting, ink hatching, masterpiece"*).
4. Swap & Re-Render: Replace the background image with your newly dreamed image. Your JSON camera pans, zooms, and speech bubbles will automatically snap onto the new artwork!- Zero-copy high performance pipeline
- Role-based access control
- Integrated OpenTelemetry distributed tracing
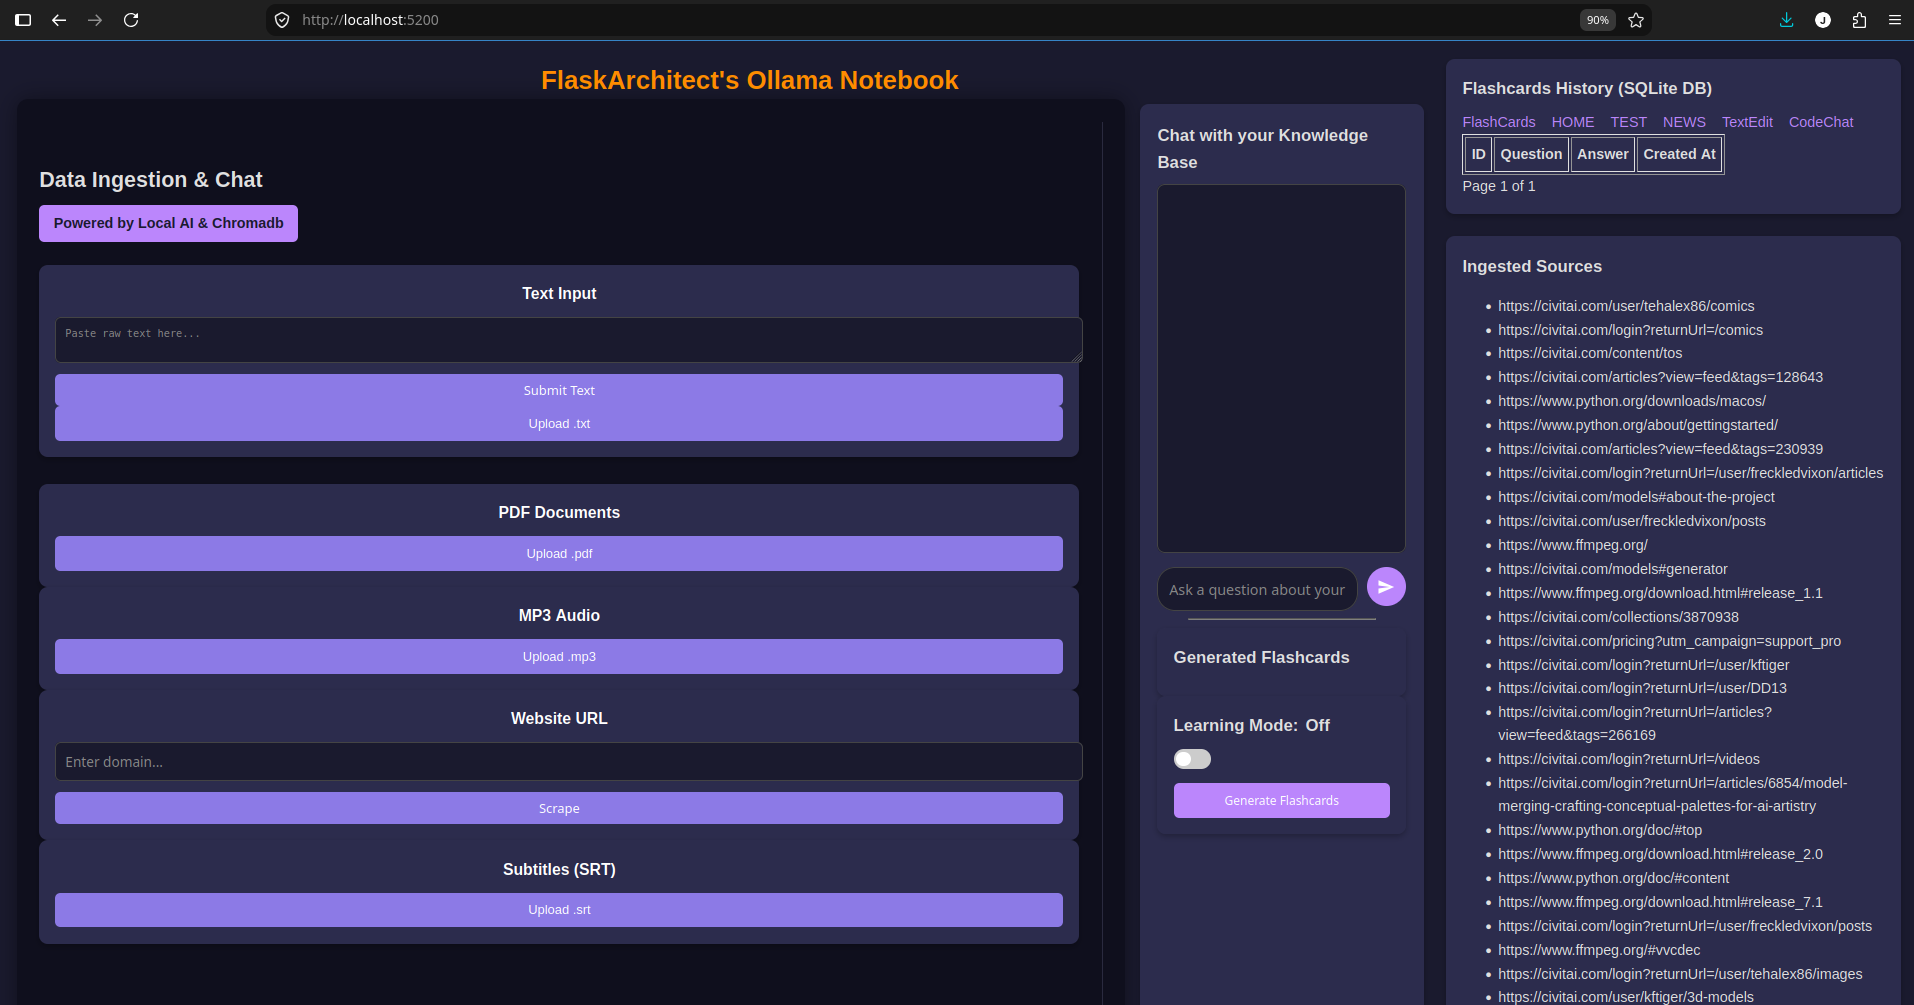
Notebooklm_lite RAG
Real-time Multi-modal LLM Assistant with SSE Streaming & RAG
system_prompt = ("You are an expert Python programmer and helpful coding assistant. "
"When generating Python code, always include comprehensive triple-quoted "
"docstrings for functions and classes, and provide type hints. "
"Include all imports, ensures directories exist and add icecream debugging"
"Ensure the code is clear, concise, and runnable.\n\n"
)
An enterprise-ready AI orchestration platform built on Flask 3.1, LangChain, and ChromaDB. Streams token-by-token LLM completions via Server-Sent Events (SSE), supports dynamic document ingestion, and implements semantic caching with Redis for 60% faster repeated queries.
- Server-Sent Events (SSE) token streaming without WebSocket overhead
- Hybrid lexical + vector similarity search with reranking
- Role-based access control (RBAC) and rate-limiting middleware
- Distributed session state managed via Redis Sentinel

VisionFlow Studio
Page, Animation, Audio, Stable Diffusion Image Generation and Video
High-performance video inference gateway using Flask, OpenCV, and YOLOv11. Processes multi-stream RTSP feeds, performs real-time bounding-box segmentation and anomaly detection, and emits telemetry over WebSockets to a skeuomorphic operator dashboard.
- Zero-copy frame buffer streaming through shared memory
- Dynamic hardware acceleration routing (CUDA / TensorRT / CPU)
- Automated temporal alert aggregation with PostgreSQL storage
- Custom polygon zone intrusion & heat-map visualization
NeuralSync Distributed Workers
Asynchronous AI Pipeline & Celery Task Worker Mesh
Distributed workflow orchestrator combining Flask with Celery, RabbitMQ, and Redis. Handles long-running batch generative AI tasks, audio transcription matrices, and image synthesis queues with automatic exponential backoff, circuit breaking, and live progress hooks.
- Dead-letter queues with automated incident auto-remediation
- Dynamic worker scaling based on queue depth metrics
- WebSocket live task progress pub/sub to web clients
- Integrated OpenTelemetry distributed tracing spans
PromptCraft Telemetry & Evaluation
LLM Prompt Versioning, Cost Telemetry & Automated Guardrails
Developer platform for testing, evaluating, and deploying robust LLM prompts across OpenAI, Anthropic, and local Ollama instances. Features token cost calculation, latency regression tracking, and automated toxicity filters.
- A/B prompt experimentation engine with semantic clustering
- Deterministic golden dataset regression suites
- Strict JSON schema enforcement with Pydantic v2 validation
- Fine-grained API key usage quota limits and billing metrics
FlaskArchitect MediaStudio
Generative Image & Video Synthesis Web Studio
MediaStudio
Media Studio is a software designed for managing and organizing multimedia content. It provides an intuitive interface for users to upload, edit, and share their media files.
The module contains several classes and functions used for working with video and audio files, including file import and export, editing capabilities, and playback controls.
It also includes tools for metadata management, such as title, description, and tags. Additionally, the module supports various file formats, including MP4, MOV, AVI, and more.
Media Studio is ideal for content creators, videographers, and audio engineers who need a user-friendly and efficient platform for managing their media assets.
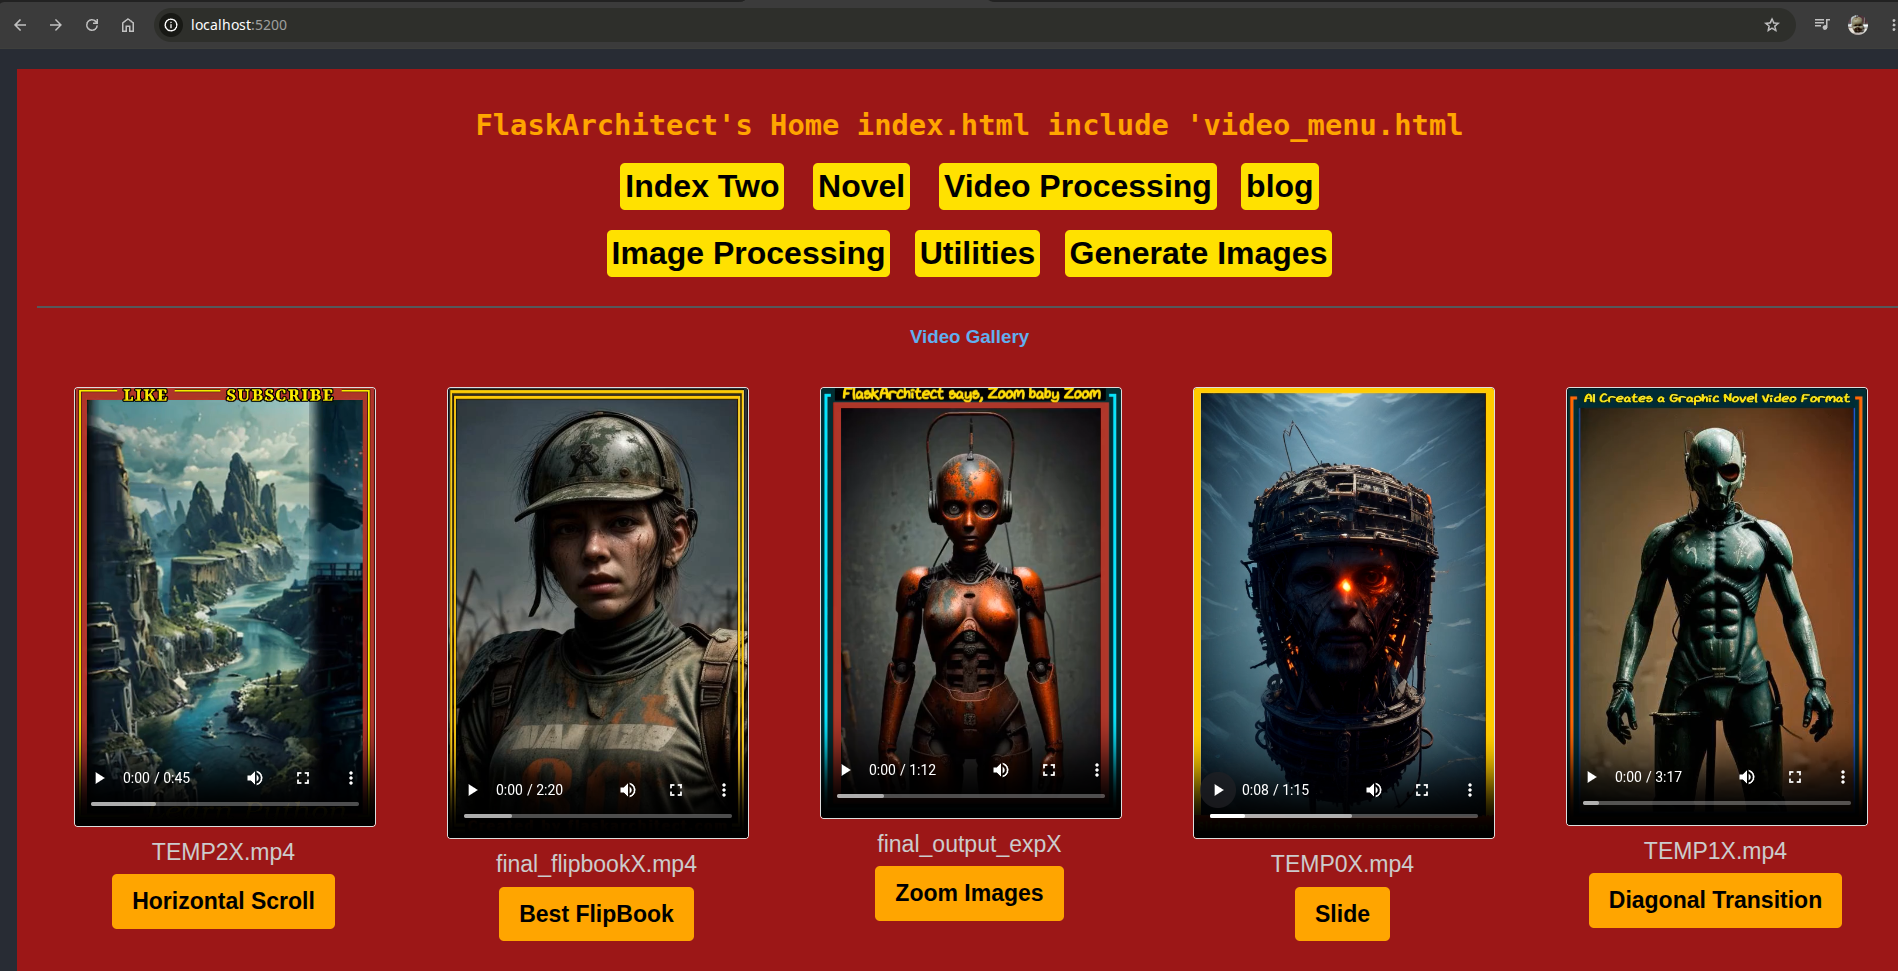
A creative asset synthesis workstation built with Flask, Diffusers, and WebAssembly image processors. Provides an intuitive studio interface for generating 4K visual assets, procedural textures, and video interpolations.
- Interactive prompt matrix generator with weight modifiers
- Integrated background removal and upscale shaders
- Direct S3 presigned upload & streaming CDN delivery
- Preset library for skeuomorphic UI textures and neural art

FlaskArchitectKnowledge RAG
Production-grade Document Intelligence & Citation Engine
Specialized Flask web service parsing complex multi-page PDFs, schematics, and financial tables. Extracts structural tables, runs hybrid BM25 + dense embedding indexing, and provides verified source-highlighted answers.
- Pixel-accurate document bounding-box citation visualizer
- Recursive chunking with context-aware semantic boundaries
- Multi-tenant vector namespace isolation
- Exportable audit reports with full grounding telemetry